We Taught a Spreadsheet to Answer Queries
Random access, GROUP BY and medians inside a compressed XLSX on S3 — the median without reading a single row. Every claim measured; two embarrassing bug stories included (one of them a claim in the first version of this very article).
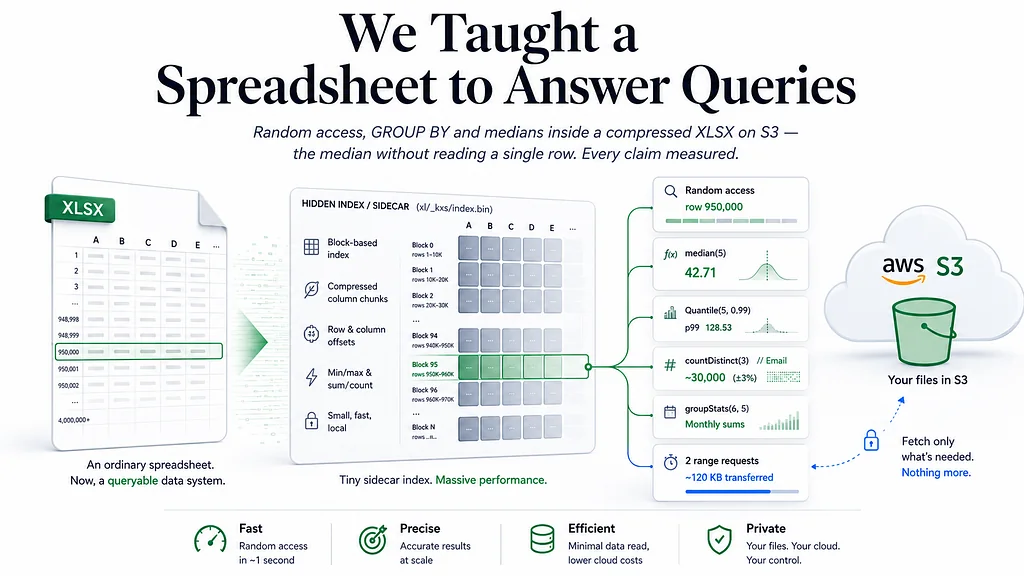
Ask any engineer what an .xlsx file is and they'll tell you: a ZIP archive full of deflate-compressed XML. Ask them to read row 950,000 of one sitting in S3 and they'll tell you the only way: download it, decompress everything before that row, and parse your way down. Compression streams are sequential. That's the deal.
Here’s what our files do instead:
$reader = StreamingXlsxReader::fromS3($s3, 'bucket', 'export-4m-rows.xlsx');

$reader->rowAt(950_000);            // ~1 second, 2 HTTP range requests
$reader->rowCount();                // instant - no scan
$reader->median('salary');          // p50 of 4M values - ZERO rows read
$reader->quantile('salary', 0.99);  // p99 - still zero rows read
$reader->countDistinct('email');    // ~distinct emails, ±3% - zero rows read
$reader->topRows('amount', 10, desc: true);       // ORDER BY amount LIMIT 10
$reader->rowsWhereAll([['amount','>',1000], ['qty','>=',5]]);  // multi-predicate AND
The file is still a completely normal spreadsheet. Excel opens it. LibreOffice opens it. Your CFO double-clicks it and sees a report. But to a reader that knows the trick, it’s something closer to a tiny, single-file data lake — over nothing but HTTP range requests.
This is the story of how kolay/xlsx-stream got there across four releases, the algorithms borrowed from genomics and column stores, and the engineering discipline that let a small package make big claims — including the discipline to publicly walk one of them back.
The problem everyone in Laravel has met
If you’ve exported large datasets in Laravel, you know the failure mode. The most popular Excel package loads workbooks through PhpSpreadsheet, whose own documentation puts memory at ~1.6 KB per cell — ten million cells is a 16 GB spreadsheet object. Queued exports are worse: the maintainer’s own guidance on the built-in queue feature is to avoid it, because it reopens the whole file on every chunk. Users report 400K-row queued exports ballooning past 900 MB.
Streaming writers (OpenSpout and friends) fixed the memory story for writing — but they write to disk before S3, and they read strictly forward: row 900,000 still costs 899,999 rows of parsing. Nothing in PHP — or honestly, in any ecosystem — gave you random access into a compressed spreadsheet.
We started there: constant ~6 MB writes streamed directly into S3 multipart uploads, no temp files. Useful, fast, but architecturally ordinary. The interesting part came next.
The trick genomics solved fifteen years ago
Bioinformatics had this exact problem: enormous gzip-compressed text files (genome data) that researchers needed random access into. Their answer — bgzip + tabix — was to compress in independently decompressible blocks and ship a small index alongside.
DEFLATE has a little-known primitive that makes the same thing possible inside a single valid ZIP entry: Z_FULL_FLUSH. A full flush byte-aligns the stream and resets the compression window — so a fresh decompressor can start cold from that exact byte offset. Excel's decompressor never notices; it reads the stream start-to-finish like always, and the flush points are invisible seams.
So the writer, in opt-in “born-indexed” mode, emits a full flush every N rows and records (row number, compressed offset, uncompressed offset) triples into a small binary sidecar — an OPC part named xl/_kxs/index.bin that no relationship references. Spreadsheet applications only traverse referenced parts, so to Excel the sidecar simply doesn't exist. To our reader, it's a seek table.
Here’s the whole trick in one picture:
ordinary.xlsx                        born-indexed.xlsx
┌──────────────────────────┐         ┌──────────────────────────────────┐
│ xl/worksheets/sheet1.xml │         │ xl/worksheets/sheet1.xml         │
│ ┌──────────────────────┐ │         │ ┌───────┬┬───────┬┬───────┬───┐  │
│ │ one long deflate     │ │         │ │ block ││ block ││ block │...│  │
│ │ stream - must be     │ │         │ │ 10K   ││ 10K   ││ 10K   │   │  │
│ │ read start-to-finish │ │         │ │ rows  ││ rows  ││ rows  │   │  │
│ └──────────────────────┘ │         │ └───────┴┴───────┴┴───────┴───┘  │
│                          │         │          ▲▲ FULL_FLUSH seams:    │
│ styles.xml, workbook.xml │         │          byte-aligned, window    │
│ [Content_Types].xml ...  │         │          reset → cold-startable  │
└──────────────────────────┘         │                                  │
                                     │ xl/_kxs/index.bin  ◄── the index │
  row 950,000?                       │  row→offset table, per-block     │
  decompress everything              │  min/max/sum, t-digest, HLL      │
  before it. every time.             │  (~KBs; unreferenced part -      │
                                     │   Excel never sees it)           │
                                     │ styles.xml, workbook.xml ...     │
                                     └──────────────────────────────────┘
                                       row 950,000?
                                       1 range GET (index) +
                                       1 range GET (its block). done.
Same bytes to Excel. A seekable, statistics-carrying container to us.
Reading row 950,000 of a multi-gigabyte file on S3 becomes: fetch the ZIP tail + sidecar (one range request), binary-search the sync points, fetch one block (second range request), inflate ~10K rows, done. The cost is bounded by the sync period — not by the file size.
That shipped in v3.0. Then we asked the obvious next question: if Parquet can skip data it doesn’t need, why can’t a spreadsheet?
Zone maps: Parquet’s best idea, smuggled into OOXML
Parquet files carry min/max statistics per row group, so query engines skip chunks that provably can’t match a predicate. Our writer already touches every value — tracking per-block min/max/sum/count for chosen columns costs a few comparisons per cell and ~13 KB of sidecar per column at 4M rows.
The reader turns that into three primitives:
$writer->withRandomAccessIndex()->withColumnStats([1, 5]);   // write side, once
$reader->columnStats('amount');                 // whole-column sum/min/max/avg - sidecar only
$reader->rowsWhere('amount', 'between', 100, 200); // skips every block whose [min,max] can't match
$reader->findRow('id', 3_141_592);              // sorted column → typically ONE block read
Real exports are almost always ID- or date-sorted, which makes these zone maps more selective than in general-purpose analytics — a point lookup on a sorted column prunes 400 blocks down to one or two. Measured on a 1M-row file in S3: findRow completes in ~1.1 s and one extra range request, independent of file size. The sequential-scan equivalent took 9.7 s and grows linearly.
The bug that taught us the format’s first law
Before shipping the query layer we ran an adversarial review against it — independent testing whose only job is to break things. It found a genuine soundness hole: the header row is written through a different code path than data rows, so it never entered the block statistics. A numeric-looking header (startFile(['999999', 'label'])) could be found by the full-scan path and hidden by the pruned path — same query, different answers.
The fix wasn’t to special-case headers in the reader. It was to make the writer fold header cells into block statistics, restoring a rule now written into the spec as normative text:
Stats widen, never narrow. Block statistics MUST account for every row the scan path can yield — a value the stats missed can hide a matching row; a value that merely widens min/max only makes pruning less selective, never incorrect.
Formats earn trust through laws like this, discovered the hard way and then pinned in conformance tests so nobody rediscovers them.
v3.2: medians without reading, GROUP BY without scanning
Zone maps answer range predicates. But the questions people actually ask a finance export are distributional: median salary, p99 order value, how many distinct customers? Exact answers need every value. Approximate answers — good to a fraction of a percent — need two classic streaming sketches:
- a t-digest (~1–4 KB per column) for quantiles,
- a HyperLogLog (2 KB) for distinct counts.
Both live in the sidecar. Both update in O(1) per value at write time. And both merge associatively — which future distributed-writing features will lean on hard. The reader answers median(), quantile(), countDistinct() with zero row reads and zero additional range requests (the sidecar arrived with the file-open handshake; our test suite pins this with a request-counting spy — the answers literally cannot touch the network).
Error bounds aren’t vibes; they’re CI assertions: p01/p99 within 0.2% rank error, distinct counts within 5% (a 50K-row live demo measured +0.51% against a known 30,000 distinct values).
groupStats() plays a subtler game. When the group column is sorted (date columns usually are), most blocks are group-pure — every row belongs to one group — so their precomputed sums are consumed straight from the sidecar and the block is never fetched. Only blocks straddling a group boundary get read. Twenty monthly groups over a million rows: ~57 ms, interior blocks provably untouched.
And the format itself is no longer ours alone: SPEC.md documents the full binary layout — TLV sections, reader invariants, security bounds — with committed conformance fixtures whose bytes are pinned in CI. Other implementations are welcome; a browser reader over fetch + DecompressionStream is the obvious first target, and that niche is empty in every language.
v3.3: the query layer grows up — and the claim we had to walk back
v3.2 could prune and estimate. v3.3 is where the query surface turned into something you’d actually reach for by reflex:
- rowsWhereAll([...]) — multi-predicate AND that intersects each predicate's surviving zone-map blocks. Two differently-clustered columns read fewer blocks together than either filter does alone.
- topRows(col, k, desc) — an indexed ORDER BY … LIMIT: on a sorted column the k extremes live at one end of the sheet, so it seeks there and reads a block instead of scanning.
- sampleRows(k, seed) — a uniform random sample drawn through the index: ≈k block reads, not a full scan. Reproducible per seed, and unbiased by construction (a chi-square gate lives in the PoC).
- estimatedRows() / explain() — zero-I/O selectivity and query plans straight from the sidecar, so you can see what a query will touch before it touches anything.
- Column addressing by name everywhere — columnStats('amount') instead of columnStats(5) — and Readers\Bucket::year()/month()/day() for calendar groupStats.
- verify() — a block-granular CRC check against the writer's per-block pins; it names the block that went bad, in O(1) memory and one inflate pass.
- compact() — opt-in r-less cells (the r attribute on <c>/<row> is optional in the spec): ~52–62% smaller compressed sheets, and faster to both write and read. Byte-identical to classic output when off; still opens in Excel/LibreOffice/Numbers and reads under PhpSpreadsheet + OpenSpout, both verified in CI.
Every one of those was built red-first and pinned against a brute-force oracle. The release also caught its own bug doing it: the sorted-column fast path behind topRows assumed row order equals value order for every row — but the "sorted" flag only ever orders numeric cells, so a sorted column with null/text cells at its end (an optional amount or discount column) returned those cells instead of the true extremes. The fix reads outward from the end, skipping non-numeric cells until it has k numeric rows; a fully-numeric end still fills on the first read. Same theme as the header bug: the pruned path must never disagree with the scan.
The claim we walked back
The first version of this article had a table (below), and next to the memory column it said the S3 writer was “flat at any row count.” That was the one claim here that turned out to be wrong, and it’s worth telling because it’s exactly the failure mode a rigorous-sounding benchmark hides.
v3.2 uploaded S3 parts through a 4-wide async window. Throughput looked great and steady-state memory looked bounded — so we called it flat. It wasn’t. The AWS SDK holds each in-flight part’s body inside a promise/command reference cycle that plain refcounting can’t reclaim, and PHP’s automatic cycle collector doesn’t fire until thousands of roots accrue. So write memory quietly grew with the file instead of staying at ~one part. The advertised “stream millions of rows to S3 with bounded memory” was, on the parallel default, silently O(file size). Our benchmark measured steady-state throughput, not the memory tail — so it never saw it.
v3.3 makes the default synchronous and reaps each settled part with one gc_collect_cycles() per 8 MB part. That call is not the CPU spike it sounds like: the collector scans only the root buffer (the handful of objects a settled part leaves, not the live heap) — measured a few milliseconds of GC work across a multi-gigabyte upload, and the free() it triggers is work owed regardless. Peak write RAM is now measured flat at ~30 MB regardless of row count. Parallel uploads remain a one-line opt-in (concurrency: 4) for high-RTT links, now GC-bounded. The read side was never affected — the streaming reader's bounded-memory promise held throughout.
“But is it actually faster?” — the replication table
Performance claims rot. So here’s the one measurement style we trust: same machine, same 3M-row workload, real S3 bucket, one fresh install per version, run back-to-back:
| Version | S3 write rows/s | Write peak RAM | S3 read rows/s | Output File |
|---|---|---|---|---|
| v3.0.2 | 134,700 | 27.6 MB | 56,828 | 124,853,536 B |
| v3.1.0 | 145,240 (+7.8%) | 29.6 MB | 57,974 (+2.0%) | identical |
| v3.2.2 | 168,744 (+25.3%) | 61.6 MB | 76,858 (+35.2%) | identical |
| v3.3.0 | unchanged | ~30 MB | unchanged | identical |
† v3.3 is a memory-and-correctness release on the write side, not a throughput play. The write and read hot paths are unchanged, so the v3.2.2 throughput numbers stand — and re-stating them from a different network session would be exactly the apples-to-oranges comparison this table exists to avoid (see the caveat below; the same 1M export has measured anywhere from 59K to 153K rows/s across sessions). The number that moves in v3.3 is peak write RAM: measured flat at ~30 MB and independent of row count, down from the 4-wide async window’s 61.6 MB — the leak fix above. On a bandwidth-bound link the synchronous default is no slower than the old parallel one (both saturate the pipe); opt into concurrency > 1 only on a high-RTT link where you've measured a win.
Two things in that table matter more than the percentages.
The output file is byte-for-byte identical across all four versions. That’s not luck — it’s method. Every hot-path optimization in v3.1 and v3.2 (a PCRE-JIT escape gate, flattened row builders, an strcspn-based tokenizer, single-pass attribute extraction) was required to prove itself against a corpus with a byte-identical diff before merging. You get +25% write and +35% read throughput, and the bytes coming out never moved. v3.3's compact() mode is opt-in precisely so this stays true by default.
The RAM column is now a dial, not a leak — for real this time. Set concurrency: 1 (the v3.3 default) and memory is flat at any row count; opt into the async window and you trade a higher, GC-bounded profile for latency-hiding on slow links. The read side pays nothing.
(The unglamorous wins add up too: rows(skip: 1_000_000) went from 3.94 s to 2.5 ms — the reader seeks instead of parsing rows it's about to throw away — and one of the read-path's biggest line items turned out to be PHP's namespace fallback on unqualified strpos() calls. A block of use function imports was worth ~5–8% by itself. Profile before you philosophize.)
What it doesn’t do (read this before the comments do)
- Only files this library writes are born-indexed. Retrofitting an index onto arbitrary XLSX files needs mid-stream inflate resumption, which pure PHP can’t do — we’ve proven it feasible via FFI (zlib’s inflatePrime), and it's on the roadmap as an optional package.
- Query predicates are numeric. Text search still means a scan (block-level trigram filters are being explored).
- Point-lookup speed assumes the column is sorted — true for most real exports, honestly degraded (still pruned, more candidate blocks) when it isn’t.
- If Excel re-saves the file, the sidecar is dropped. The reader detects this via CRC pinning and silently falls back to sequential scans — wrong answers are not on the menu, but the speedup is gone until you re-export.
- Absolute S3 numbers belong to your network path, not the library. The same 1M-row export has measured anywhere from 59K to 153K rows/s across sessions on the same machine. Trust same-link A/Bs (like the table above); benchmark your own link — the harnesses ship in the repo.
Try it
composer require kolay/xlsx-stream:^3.3

// A queued Laravel export: constant memory, straight to S3, born queryable
$writer = SinkableXlsxWriter::forDisk('s3', 'exports/huge.xlsx')
    ->queryable([1, 5, 3]);   // index + zone maps + sketches in one call
$writer->startFile(['ID', 'Name', 'Email', 'Phone', 'Amount']);
User::query()->lazyById(1000)->each(
    fn ($u) => $writer->writeRow([$u->id, $u->name, $u->email, $u->phone, $u->amount])
);
$writer->finishFile();
…and the payoff, from any other process, any other day — the file never comes down from S3:
use Kolay\XlsxStream\Readers\Bucket;

$reader = StreamingXlsxReader::fromS3($s3, 'bucket', 'exports/huge.xlsx');
$reader->rowCount();                         // instant
$reader->median('Amount');                   // p50 amount - zero rows read
$reader->countDistinct('Email');             // ~unique emails, ±3%
$reader->findRow('ID', $userId);             // one block, ~2 range requests
$reader->topRows('Amount', 10, desc: true);  // ORDER BY amount DESC LIMIT 10
$reader->verify();                           // block-granular CRC check
foreach ($reader->rowsWhereAll([['Amount','>=',10_000], ['ID','<',500_000]]) as $n => $row) {
    // only blocks whose [min/max] can satisfy BOTH predicates were fetched
}
// monthly sums with a sorted date column - interior blocks read from the sidecar, unread:
foreach ($reader->groupStats('created_at', 'Amount', Bucket::month()) as $g) {
    // $g = ['group' => 202601, 'sum' => …, 'count' => …, 'min' => …, 'max' => …]
}
// fan an import out to 8 queue workers, zero coordination:
foreach ($reader->shards(8) as $shard) {
    ProcessShard::dispatch('bucket', 'exports/huge.xlsx', $shard);
}
Everything above — 607 tests / 7565 assertions, the spec, the conformance vectors, the benchmark harnesses, and the changelogs that admit which bugs the adversarial reviews caught (the header-stats hole, the S3 memory leak, the sorted-column null) — is in the repo: github.com/turgutahmet/kolay-xlsx-stream.
The spreadsheet has been the world’s most-used database for thirty years. It just never had an index. Now it does — and the format is open, so it doesn’t have to stay a PHP trick.